
Press Release
Big Data Terminology Sets Three World Firsts

– Interview with Professor Lian Yuming, chief editor of Big Data Terminology and director of the Key Laboratory of Big Data Strategy
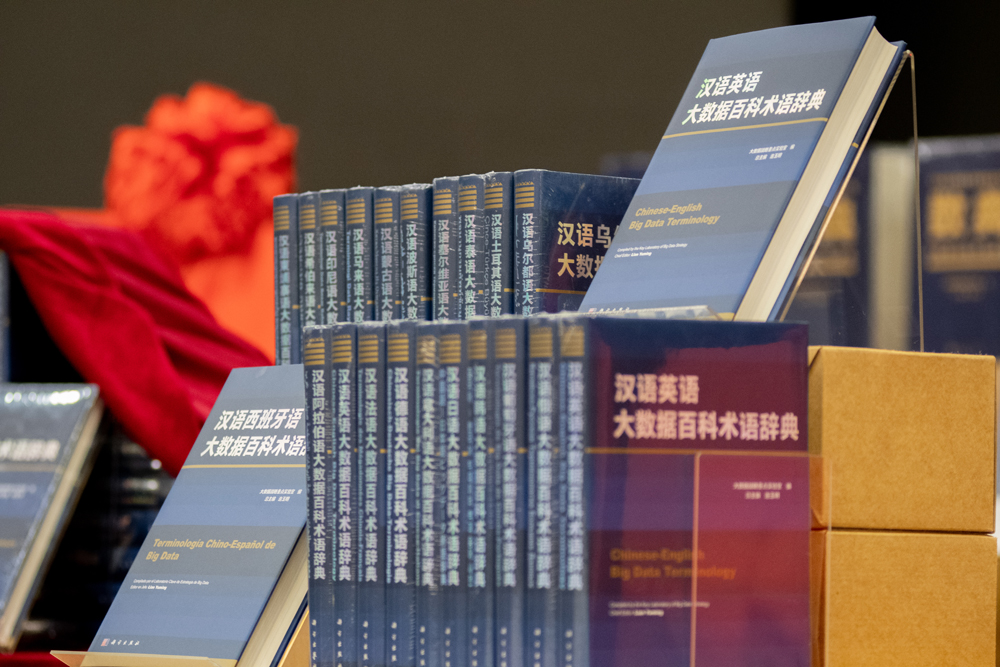
Editor’s note: Big Data Terminology (20 Volumes), the world’s first smart multilingual terminology series that systematically deals with different aspects of big data, was published in May 2021 by Science Press and distributed globally. To better explore its compilation process, creative content and contemporary value, the reporter conducted an exclusive interview with Professor Lian Yuming, chief editor of the series and director of the Key Laboratory of Big Data Strategy.
Reporter: Big Data Terminology is the world’s first smart multilingual terminology series that systematically deals with different aspects of big data. Could you please introduce the background of its compilation?
Lian Yuming: In today’s world, information technology is getting advanced with each passing day. Digitization, networking, and intelligent technology are developing fast. Following agricultural civilization and industrial civilization, humanity is entering the era of digital civilization and there is an urgent need for rules governing it. As the core area of China’s first national big data comprehensive pilot zone, Guiyang has introduced the concept of big data terminology, launched a big data terminology project, and compiled the world’s first multilingual big data terminology series. These endeavors aim to build a standardized terminology system for big data, to shape the public discourse system, to facilitate communication between industries and sectors, and to help people around the world to grasp the opportunities brought by digitalization, networking, and intelligent technology, and properly handle legislation, security, and governance challenges faced by the big data industry.
As the linguistic representation of scientific knowledge, terminology is a kind of foundational information resource that supports the scientific, technological, and academic discourse system. It is an epitome of what human wisdom has produced and maps out the trajectory of science, technology and human progress. In Erya, China’s first encyclopedic dictionary, 16 of the 19 categories focus on nouns; Dream Pool Essays was the first to give the name shiyou (petroleum), and the term remains in use today. The scientific and technological terms that have been passed down since ancient times reflect the deep thoughts given by sages to naming scientific and technological concepts and have made indelible contributions to cultural inheritance and scientific and technological exchanges in history. Major changes unseen in a century are taking place in our world. Disruptive technologies follow one another, and new concepts, theories and methods continue to emerge. A long-term focus on the standardization of scientific and technological terms in the new era is to serve cutting-edge basic research as well as new scientific fields and systems.
Big Data Terminology is the world’s first smart multilingual terminology series that systematically deals with different aspects of big data. It is compiled by the Key Laboratory of Big Data Strategy, in cooperation with dozens of professional institutions and hundreds of experts in and outside of China. Big Data Terminology claims three world firsts: (i) It represents the world’s first big data terminology system that is unified, standardized, and conforming to international principles, and all entries have been reviewed by an expert panel of China National Committee for Terminology in Science and Technology; (ii) it is the world’s first big data terminology written in 21 languages, including languages used in the countries along the Belt and Road; and (iii) it is the world’s first big data terminology that comes with a multilingual audio database and audio book feature. In light of big data development around the world, Big Data Terminology establishes a standardized system of concepts that covers many languages with the Chinese terminology as the basis, aiming to advance rulemaking and drive innovation and the development of global digital civilization.
Reporter: Big Data Terminology is a major innovation in the frontiers of science and technology. How did your team ensure its content is forward-looking, professional and innovative during the research and compilation process?
Lian Yuming: As you said, Big Data Terminology is an outcome of globalized, interdisciplinary, professional, and open research efforts. It is an important innovation in the frontiers of science and technology, claiming several world firsts. During the research and compilation process, we encountered a lot of challenges. We paid attention to resource integration and mechanism innovation and worked with the most professional teams to control the entire process of research, review, translation, and publication in accordance with the most stringent standards to ensure the content is forward-looking, professional and innovative.
Big Data Terminology is compiled by the Key Laboratory of Big Data Strategy, in cooperation with dozens of professional institutions and hundreds of experts in and outside of China. The five major research centers of the laboratory gave full play to their strength in platforms and the experts contributed their expertise during the research and compilation process. Entries are selected by experts from authoritative databases, including Science Citation Index (SCI), Social Science Citation Index (SSCI), Engineering Index (EI) and Index to Scientific & Technical Proceedings (ISTP). The underlying corpus is formed on the basis of big data literature on the CNKI platform. Great efforts are made to ensure the entries are accurate, scientific, and of great utility based on experts’ research findings. China National Committee for Terminology in Science and Technology organized a team of top experts from the Chinese Academy of Sciences and other related institutes across the world to review the terminology. More than 60 experts from the Chinese Academy of Sciences, the Academy of Military Science, the State Information Center, International Knowledge Centre for Engineering Sciences and Technology (IKCEST) under the Auspices of UNESCO, Peking University, Tsinghua University, Renmin University of China, Zhejiang University, China University of Political Science and Law, University of Wisconsin, China Institute of Communications, China Academy of Information and Communications Technology, and China National Institute of Standardization submitted written review opinions, and more than 10 special review meetings were held. Global Tone Communication Technology Co., Ltd., the only language service provider in China that is rated 5A for its translation service, was responsible for the translation and revision of the series. The company has made great efforts to deliver faithful, reliable and accurate translations. Translations are reviewed strictly to ensure faithfulness to the original texts, accuracy, correctness, and readability. Work has also been done to ensure that entries are ordered and indexed in accordance with clearly defined rules, the terms with Chinese characteristics and the newly created scientific and technical terms are carefully translated on the basis of adequate research, the difficult terms are translated with utmost accuracy, and the culturally sensitive terms are handled correctly. Big Data Terminology is published by Science Press, which in itself is a manifestation of authority. China Science Publishing & Media Ltd. (CSPM) is China’s largest science publishing company and one of the country’s three largest publishing and media groups. As a publishing organization of the Chinese Academy of Sciences, its professionalism, strict quality control, and rigorous publishing process are well-known in the publishing industry. During the publication process, Big Data Terminology was designated as a key national publication project during the 14th Five-Year Plan period (2020-2025). The publishing company has made every effort to ensure professionalism, accuracy and standardization in publication and distribution of the terminology.
Reporter: Big Data Terminology is the world’s first smart multilingual terminology series that deals with different aspects of big data. What are the characteristics and highlights of the terminology?
Lian Yuming: The 20-volume Big Data Terminology series marks another innovation of the National Big Data (Guizhou) Comprehensive Pilot Zone after the original eleven-language edition. It is an important symbol of the growing global influence of China’s innovations in big data theory and standardization. Big Data Terminology has four main characteristics: it is presented as an encyclopedia; it is reviewed by authoritative experts; it covers many languages; and it delivers a smart experience.
Like an encyclopedia, Big Data Terminology deals with different aspects of the subject of big data. It presents information that is considered forward-looking in the global context and organizes such information into nine categories: basics of big data, big data strategy, big data technology, big data economy, big data finance, big data governance, big data standards, big data security, and big data law. Together, they comprise a multilingual academic discourse system that is unified, standardized, and conforming to international principles.
China National Committee for Terminology in Science and Technology has organized a team of top experts from the Chinese Academy of Sciences and other related institutes across the world. The experts reviewed the entries in their respective field according to theCommittee’s Principles and Methods for the Review of Terms in Science and Technology.
As one of its innovative features, this series includes 20 bilingual volumes, each having its content presented in Chinese and another language (Arabic, English, French, German, Italian, Japanese, Korean, Portuguese, Russian, Spanish, Cambodian, Hebrew, Indonesian, Malay, Mongolian, Persian, Serbian, Thai, Turkish and Urdu). It aims to provide knowledge in a convenient, accurate, and smart way, and to further foster the dissemination of the standard big data terminology system among people from different linguistic and geographical backgrounds.
The series includes innovative features such as knowledge graphs, audio books, and platform links, thus allowing readers to have a smart, platform-based and systematic experience. On the basis of continuous research, the Global Sharing Platform for Big Data Language Services was developed. All the multilingual resources and services on this platform are provided for free to people around the world via Big Data Terminology Cloud, Silk Road Big Data Terminology, Big Data Terminology Online, Big Data Terminology Guiyang Index, and Big Data Terminology Library.
Reporter: What will the project team do after the publication of Big Data Terminology?
Lian Yuming: The publication of Big Data Terminology is a milestone for the big data terminology project. On this basis, we are now carrying out follow-up actions in three areas to promote international dissemination and application of the project outcomes and drive the development of global digital civilization.
First, we are developing standards with Big Data Terminology at the core to increase our influence in big data standardization. We will continue to deepen the research on the basis of the eleven-language edition and the 20-volume edition of Big Data Terminology to support the formulation of the Handbook on Standard Big Data Terminology in the Official United Nations Languages, promote communication across languages in terms of big data technology and knowledge, and facilitate connectivity between the world’s major countries. We will also continue to promote international dissemination and application of big data terminology in a wider range and broader fields, and tell stories about China well.
Second, we are building an index system on the basis of the Big Data Terminology Guiyang Index, seeking to present the grand picture of big data development. We will, via the Big Data Blue Paper and based on continuous research efforts, continue to update and release information on the Big Data Terminology Guiyang Index which consists of six sub-indexes: the global digital competitiveness index, big data development index, big data security index, law-based big data governance index, big data financial risk control index, and governance technology index. We will use the indexes to comprehensively measure and evaluate China’s performance in big data development, and support China’s effort to increase competitiveness and participation in world governance.
Third, we are building a system of platforms around the Global Sharing Platform for Big Data Language Services to increase our international influence in the field of big data. We will continue to improve Big Data Terminology Cloud, Silk Road Big Data Terminology, and Big Data Terminology Online which have the big data terminology, audio database, knowledge base, and corpus at the core. We will also build the Big Data Terminology Guiyang Index platform which is supported by the index-related data, and Big Data Terminology Library supported by the knowledge base. Our goal is to build the Global Sharing Platform for Big Data Language Services into a dynamic open-source database and an open platform covering widely spoken languages in the world, to provide knowledge in a convenient, accurate, and smart way, and to promote dissemination and application of “Chinese knowledge” on a global scale.
Reporter: Big Data Terminology has facilitated international communication between industries and sectors. What positive impact will this have on the Data Valley Guiyang, on China and on the world?
Lian Yuming: As far as Guiyang is concerned, it will further promote the visibility and international influence of China Data Valley. In the era of globalization, terminology is playing an important role in scientific and technological competition and the contest for influence. Guiyang is the core area of China’s first big data comprehensive pilot zone and, in conjunction with China National Committee for Terminology in Science and Technology, is the first to carry out innovative research in, and intelligent promotion of, terminology standardization, which plays a unique and irreplaceable role in enabling scientific and technological development and rulemaking. In particular, Big Data Terminology is expected to greatly enhance China’s international influence in the field of big data and relevant rulemaking. Meanwhile, the publication of Big Data Terminology will also support higher-level opening up of Guizhou and Guiyang and help Guiyang become a stronger provincial capital.
From a national perspective, it will help China increase its international influence in the era of digital civilization. Language holds the key to communication and to the future, and breaking down language barriers is crucial for promoting the dissemination of “Chinese knowledge” and increasing international influence in the era of big data. Through Big Data Terminology, we have established a standardized system of concepts that covers many languages with the Chinese terminology as the basis. It aims to promote the standardization of big data terms worldwide, to provide knowledge in a convenient, accurate, and smart way, and to further foster the dissemination of the standard big data terminology system among people from different linguistic and geographical backgrounds. It is an important symbol of the growing international influence of China’s innovations in big data theory and standardization. According to the National Committee for Terminology in Science and Technology, the publication of Big Data Terminology is expected to greatly enhance China’s international influence
in the field of big data and relevant rulemaking, contributing significantly to the high-quality
development of big data in China and around the world, as well as promoting the international
dissemination of big data knowledge and exchange and cooperation in relevant fields.
From a global perspective, it will play a positive role in promoting the Belt and Road Initiative (BRI) and building a community with a shared future for mankind. On the foundation of the eleven-language edition of Big Data Terminology, which is also the first of its kind, this series now covers more languages, systematically presenting its content in Chinese and 20 other languages: Arabic, English, French, German, Italian, Japanese, Korean, Portuguese, Russian, Spanish, Cambodian, Hebrew, Indonesian, Malay, Mongolian, Persian, Serbian, Thai, Turkish, and Urdu. These languages cover the Sino-Tibetan, Indo-European, Altaic, South Asian, Asian-African, and Austronesian language families and can reach out to readers on six continents around the world, promote international dissemination and application of big data, especially in countries along the Belt and Road, and drive the development of the digital economy. The Alliance of International Science Organizations (ANSO) believes that the series provides an authoritative template for people in the BRI countries and regions, as well as the world, to better understand a digital China and that it embodies a care for the shared future of mankind..
About Author

Disclaimer: The views, suggestions, and opinions expressed here are the sole responsibility of the experts. No Digi Observer journalist was involved in the writing and production of this article.

Press Release
CoinRabbit Wins “Best Crypto Lending Platform 2026” Award from International Business Magazine

Toronto, Canada, September 4th, 2026, Chainwire
CoinRabbit has been named Best Crypto Lending Platform 2026 by International Business Magazine, highlighting a lending product that has issued more than $1.45 billion in loans since 2020.
About the International Business Magazine Award
The International Business Magazine Awards recognize companies and executives making a significant impact across global industries. The selection process combines public nominations with jury review, with nominees assessed on their work, progress, and contribution to their respective industries.
For CoinRabbit, the award comes at an important stage in the company’s development. It is moving beyond borrowing against crypto and building a broader ecosystem for managing digital-asset capital.
Why CoinRabbit Was Named the Best Crypto Lending Platform
The Best Crypto Lending Platform 2026 award recognizes the work CoinRabbit has put into its ecosystem. The platform provides borrowers with fast access to liquidity and confidence that their funds remain secure. CoinRabbit maintains a clear no-rehypothecation policy, giving clients greater certainty that their collateral is not being reused or lent out elsewhere.
That focus on a predictable borrowing experience has remained central as CoinRabbit has expanded the product. There is no traditional credit check because crypto collateral does the underwriting, and the lending process takes about 10 minutes whether a client is borrowing a few hundred dollars or managing a six-figure position.
The award jury also highlighted CoinRabbit’s Private Program as a high-touch approach for clients with significant balances. Designed for portfolios of $500,000 and above, it offers a more personalized way to manage assets around each client’s financial goals, liquidity needs, and timing. As part of CoinRabbit’s broader digital-asset ecosystem, the program gives clients a more private banking-style experience.
Capital Preservation at the Core
CoinRabbit is expanding into capital management, but lending remains at the core of the business. By giving clients access to liquidity without a need to sell their crypto, it helps preserve capital and keep assets invested for the long term.
Walter Barrett, Chief Strategy & Growth Officer at CoinRabbit, commented:
“We’ve spent years building and refining the product, and it’s rewarding to see that work recognized. At the same time, CoinRabbit is becoming more than just a lending platform. With the Private Program, we’re bringing a private credit approach to managing crypto. Clients can work directly with a success manager to find the right strategy for their needs, with a more tailored way to build crypto capital. We also continue to improve the core lending product, keeping it simple. For us, the goal is to make both sides of the business stronger as we grow.”
As CoinRabbit evolves, capital preservation remains a central idea behind the company’s products and services.
About CoinRabbit
CoinRabbit is a crypto asset management platform built for long-term capital preservation. It provides flexible liquidity management across multiple environments. Instant payments and lending, yield and trading products, and also the Private Program are available from a single platform. Since 2020, CoinRabbit has maintained a 100% capital reserve model, ensuring that client assets are fully reserved and never rehypothecated.
Contact
CoinRabbit
marketing@coinrabbit.io
About Author

Disclaimer: The views, suggestions, and opinions expressed here are the sole responsibility of the experts. No Digi Observer journalist was involved in the writing and production of this article.
Chicago, United States, September 4th, 2026, Chainwire
Liquid Mercury today announced that ACQUA1, LLC completed the initial closing of its MERC exchange offering on September 1, 2026.
ACQUA1 is a Liquid Mercury subsidiary that operates Liquid Mercury’s Lab Company program, licensing Liquid Mercury technology to companies primarily tokenizing real-world assets and receiving fees plus a minority equity stake in return. Liquid Mercury is the majority holder and Manager.
“Over the past 18 months, dozens of companies have approached Liquid Mercury seeking to tokenize their assets,” said Tony Saliba, CEO and founder of Liquid Mercury. “Many assumed they would need to raise capital and build this infrastructure from scratch. Licensing Mercury RWA lets them launch on systems that were already live and proven, at a fraction of the time and cost. ACQUA1 token holders now own a slice of the business that earns equity, plus fees from the companies in the Lab Company program.”
Verified accredited investors subscribed by exchanging MERC for non-voting Class B units of ACQUA1 at the initial conversion rate of 10 MERC per unit. Under its operating agreement, ACQUA1 must burn 100% of the MERC it receives at each closing within five business days and may not transfer, trade, lend, stake, pledge, or otherwise deploy it.
On September 2, all 563,230,000 MERC received at the initial closing were burned via a transfer to the dead address, as the offering documents require.
Initial Closing Highlights
- Initial closing: September 1, 2026
- MERC burned: 563,230,000
- Transferred to the dead address September 2, 2026
- Units issued: 56,323,000
- Non-voting Class B units of ACQUA1, LLC under Rule 506(c) of Regulation D
- 10 MERC per unit
- Evidenced on-chain by ACQUA1-C tokens
- ACQUA1-C tokens convert one-for-one into ACQUA1 tokens upon issuance
- Remaining closings: On or about October 30 and December 31, 2026
- ACQUA1 may skip or terminate at its discretion
- The conversion rate at subsequent closings may differ
Verification Links
Verified accredited investors can request full terms at acqua1.liquidmercury.com/contact.
About Liquid Mercury
Liquid Mercury powers professional crypto trading and digital asset marketplaces. The company delivers institutional-grade infrastructure, access to deep liquidity, and best-in-class trading tools and workflow automation across its Pro, OTC, and RWA platforms. Through Mercury RWA, Liquid Mercury is extending that infrastructure into tokenized real-world assets, with $MERC serving as the access and platform layer token. For more information, visit www.liquidmercury.com.
Investor Notice
This press release does not constitute an offer to sell or the solicitation of an offer to buy any securities. Class B units of ACQUA1, LLC and the ACQUA1 tokens representing them are offered and sold in reliance on the exemption from registration provided by Rule 506(c) of Regulation D under the Securities Act of 1933, solely to verified accredited investors as defined in Rule 501(a) of Regulation D, and solely pursuant to ACQUA1’s confidential private placement memorandum, as supplemented, and definitive subscription documents, which contain important information, including risk factors. ACQUA1 tokens are restricted securities, are subject to transfer restrictions under ACQUA1’s operating agreement and may remain illiquid indefinitely; investors should not assume that Rule 144 will be available. Statements regarding future revenues, valuations, portfolio performance, and subsequent closings are forward-looking and subject to risks and uncertainties; actual results may differ materially. The MERC contract has no burn function; tokens are removed from circulation by transferring to the dead address. Supply outstanding excluding the dead address is 5,436,770,000 MERC, as of the date of publication.
Contacts
Director
Kent Egan
Liquid Mercury
ke@liquidmercury.com
Director
Ryan Hansen
Liquid Mercury
hansenr@liquidmercury.com
About Author
Disclaimer: The views, suggestions, and opinions expressed here are the sole responsibility of the experts. No Digi Observer journalist was involved in the writing and production of this article.
Press Release
Cracking 1.33 Trillion Daily Tokens: B.AI Powers the “AI Grid” with Full-Stack Infrastructure to Fuel the Agentic Era

Singapore – B.AI, a next-generation AI infrastructure platform, recently set off a developer frenzy by offering free access to top-tier models. Within days, daily token throughput across the platform crossed 1.33 trillion—a historic milestone.
The record-breaking figure underscores the campaign’s explosive rollout, but it marks only the first step in B.AI’s broader strategic roadmap. Moving beyond traditional compute distribution pipelines, B.AI aims to build the global settlement layer for intelligence: a core infrastructure hub engineered to power cross-node collaboration, orchestration, and value distribution for AI agents across complex business workflows.
Positioning itself strategically above all models, below all agents, B.AI deeply integrates a diverse range of top-tier models with full-stack components, laying an unshakable, irreplaceable foundation for the mass adoption of autonomous agents and the productivity boom that follows.
Daily Token Throughput Tops 1.33 Trillion: B.AI’s Free Access Rollout Fuels Usage Boom
B.AI’s recent move to open free access to premium AI models has captivated developers and quickly taken over industry conversations. The push for accessible compute has not only fueled a surge in platform activity but also shattered usage records.
In a matter of days, soaring API demand pushed the platform’s daily token throughput past a staggering 1.33 trillion. Over a 15-day window, cumulative volume reached 8.19 trillion tokens, drawing in more than 220,000 new API users. As of September 3, B.AI’s total user base had officially surpassed 2.3 million.
That massive adoption traces directly to the platform’s zero-cost model lineup, a strategic rollout built to erase developers’ cost concerns. With every barrier removed, B.AI now offers unlimited free access to six leading frontier models: DeepSeek-V4-Flash, DeepSeek-V4-Flash-Vision-Exp, Tencent Hy3, Xiaomi MiMo-V2.5, GLM-5.3-Flash (Ox Alpha), and Qwen3.8-Flash.

Notably, on September 3, B.AI rolled out a new pricing structure for DeepSeek-V4-Flash and DeepSeek-V4-Flash-Vision-Exp, introducing tiered discounts. Developers now receive a 50% discount during peak hours, with off-peak rates dropping to just 25% of standard peak pricing. At the same time, the platform has kept zero-cost access in place for GLM-5.3-Flash (Ox Alpha), Qwen3.8-Flash, Tencent Hy3, and Xiaomi MiMo-V2.5. Despite the shift toward commercialization, developer momentum hasn’t wavered, with platform-wide token throughput continuing its steady climb.
This sustained momentum proves the campaign was far more than a short-term compute giveaway—it is a bellwether for the broader evolution of AI infrastructure. Cracking 1.33 trillion daily tokens makes one thing clear: AI applications are moving past basic chatbots. Powered by a high-performance technical stack and flexible service mechanics, B.AI is laying the groundwork for the next frontier—autonomous AI agents operating at scale.
Powering the “AI Grid”: B.AI Anchors the Global Settlement Layer for the Agent Economy
For B.AI, democratizing compute is only the prelude. Looking further ahead, the platform is committed to building full-stack infrastructure for the agentic era, cementing its position as the global settlement layer for intelligence.
In the agent era, a typical agent task calls for constant switching between models. No single provider can power a complete workflow on its own, so developers are left juggling fragmented API protocols, disjointed billing systems, and conflicting rate limits.
B.AI’s settlement layer bridges this exact gap. Positioned strategically “above all models, below all agents,” B.AI abstracts models across different providers, capabilities, and cost structures into a unified pool of schedulable resources.
Powered by a dual-tier API structure offering official-route reliability alongside lowest-cost custom channels, developers can choose between guaranteed direct connections and deeply discounted options across a broad lineup of models. Combined with smart routing on the Chat interface, B.AI operates as a full-stack “AI grid,” ensuring every agent request lands on the optimal model to deliver reliable performance at maximum cost-efficiency.

On the settlement front, this power grid seamlessly bridges both Web2 and Web3 models. For Web2, developers can rely on familiar traditional payment methods to top up with minimal friction. For Web3, B.AI leverages on-chain payment rails to offer global developers decentralized, verifiable, and low-friction payment options.
With dual payment systems running in parallel, B.AI enables developers and agent applications across any infrastructure setup to find their optimal settlement path on the grid, providing single-point integration with borderless global reach.
Driving Core Productivity: B.AI Reshapes Agent Collaboration
Beyond building a foundation for compute routing and global settlement, B.AI is moving past base infrastructure to power real-world productivity. By enabling seamless agent collaboration across complex workflows, it delivers the missing execution layer for the agent economy.
At the heart of this execution layer is native Codex integration. Full compatibility with the Responses API means developers can now use a single B.AI key inside Codex to run flagship GPT models and DeepSeek favorites side by side.

Engineers can now bring these powerhouse models straight into their daily dev stack. From code generation and reasoning to debugging and refactoring, B.AI unifies the entire workflow under one roof—delivering a direct line from model selection to shipped code.
Beyond coding, to keep agents running reliably in real-world production at scale, B.AI has built a full-stack infrastructure powered by five core components, equipping agents with a fine-tuned operational engine:
- x402 Payment Protocol: Introduces an innovative “pay-before-response” model that executes high-frequency, on-chain micro-settlements in the background during cross-agent API calls and compute orchestration.
- 8004 Identity Protocol: Issues verifiable on-chain credentials for every agent, logging execution history and credit scores to establish a reliable layer of trust for cross-node collaboration.
- Skills Matrix: Plug-and-play, standardized building blocks that interface directly with MCP servers to equip agents with instant, modular tool-calling capabilities.
- BAIclaw and BAIcode: Built-in platform assistants engineered for end-to-end execution. BAIclaw manages all-in-one terminal operations and multi-agent workflows, while BAIcode serves as an advanced developer engine that streamlines the full pipeline from task analysis and architecture design to coding and testing.
From the token surge sparked by zero-cost model access to its positioning as the global settlement layer for intelligence; from seamless Codex integration to full-stack infrastructure powered by x402, 8004, Skills, and native assistants—B.AI delivers far more than a battle-tested technical stack; it unveils a clear blueprint for what lies ahead. B.AI is building not just accessible compute today, but the definitive launchpad for a thriving agent economy. The future is here—and this is only the beginning.
B.AI Team
support@b.ai
About Author
Disclaimer: The views, suggestions, and opinions expressed here are the sole responsibility of the experts. No Digi Observer journalist was involved in the writing and production of this article.
CoinRabbit Wins “Best Crypto Lending Platform 2026” Award from International Business Magazine
Liquid Mercury Announces Initial Closing of ACQUA1 Offering
Cracking 1.33 Trillion Daily Tokens: B.AI Powers the “AI Grid” with Full-Stack Infrastructure to Fuel the Agentic Era
Benzinga Money Article Discusses How to Become Part of the 12% of Retirees Who Have Achieved the Recommended $550,000 Minimum Retirement Savings Threshold
Apu Apustaja Conquers New York with Lively Street Ads, Including Times Square Billboard
Bay Smokes Maintains Quality Amid Legislative Changes in the Hemp Industry

-
Press Release2 days ago
SignalHandy Launches AI-Powered Reddit Monitoring Platform to Help Businesses Find Customers
-
Press Release6 days ago
Clayton Fields Identifies Questions to Ask Before Replacing Proven Technology
-
Press Release6 days ago
Why Full-Mouth Rehabilitation Requires More Than Replacing Missing Teeth
-
Press Release6 days ago
Flora Dong Discusses the Role of Human Judgment as AI Enters Wealth Management
-
Press Release6 days ago
Post Oak Group Weighs In on Private Credit’s Expanding Role in Middle-Market Financing
-
Press Release6 days ago
Aquashield Roofing Corporation Delivers Specialized Shingle and TPO Roofing Solutions to Residential and Commercial Clients in Hampton Roads
-
Press Release5 days ago
DeXenY Expands Its Decentralized Energy Vision to a Wider Web3 Audience as $DXY Prepares for Bitvoux Launch
-
Press Release6 days ago
BOOMFIT PREMIUM Krasnodar Severny hosts a superhero-themed promotional event